
Researchers publish thousands of neural network papers annually. Yet, almost none of these models end up in the hands of actual users. A massive graveyard of failed AI startups sits right between the academic lab and the commercial market. Moving neural networks to market demands much more than brilliant algorithms. Founders must transform a fragile academic script into a reliable, scalable technology that solves a specific, painful problem.
Take a fictional researcher, Dr. Chen. She publishes a paper on a new neural architecture that crushes benchmark scores. The paper gets cited hundreds of times. Three years later, her model still sits on GitHub, unused. Meanwhile, a clunkier model from a different team serves millions of daily active users. Why? The answer lies in the five stages of commercialization-and why most models die before stage two.
Take a fictional researcher, Dr. Chen. She publishes a paper on a new neural architecture that crushes benchmark scores. The paper gets cited hundreds of times. Three years later, her model still sits on GitHub, unused. Meanwhile, a clunkier model from a different team serves millions of daily active users. Why? The answer lies in the five stages of commercialization-and why most models die before stage two.
The Five Stages of the Crossing
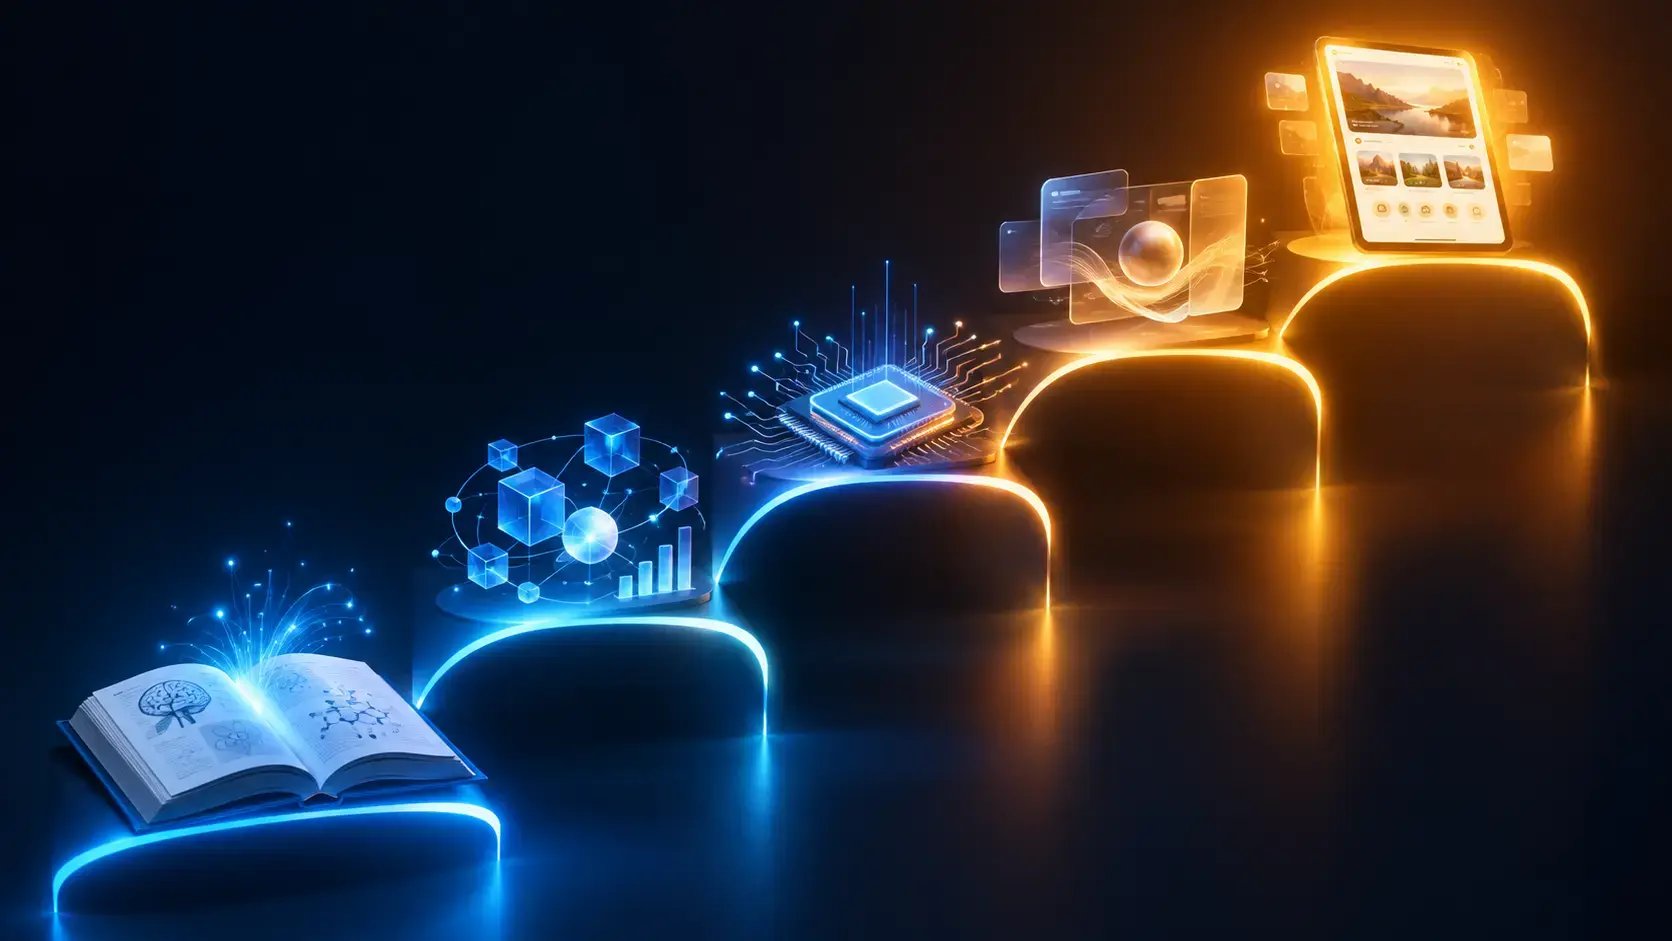
The journey from research to revenue is not a straight line. It is a treacherous path with five distinct stages: research paper to reproducible model, reproducible model to shippable product, product to scaled system, and scaled system to market position. Each stage has its own challenges, skill requirements, and failure modes. Most AI companies do not fail because their technology is bad. They fail because they try to skip stages or apply the wrong mindset at the wrong time. We will walk through each stage honestly-what it takes, what breaks, and what the successful crossers do differently.
A Short History: How Neural Networks Learned to Leave the Lab
The story of neural networks leaving the lab starts in 2012. That year, a convolutional neural network called AlexNet won the ImageNet competition with a 15.3% error rate, crushing the competition and proving that deep learning actually worked on real-world problems. This was not just a research milestone. It was the moment the industry realized neural networks could do something useful.
Five years later, in 2017, the "Attention Is All You Need" paper introduced the transformer architecture. Transformers made the same basic architecture handle language, vision, and eventually code. This made neural networks more general-purpose, more scalable, and easier to deploy across different domains.
Then came 2020 and GPT-3. With 175 billion parameters, it was the largest neural network anyone had seen. More importantly, OpenAI released it as an API. This shifted the commercialization pattern from "we trained a model" to "we ship a product." Developers could suddenly access state-of-the-art AI without training anything themselves.
The next wave hit in 2023-2025: the open-source explosion. Meta's Llama family, Mistral, and others made powerful models freely available. Suddenly, the bottleneck was not access to models. The bottleneck was everything else: infrastructure, product design, distribution, and unit economics. The question was no longer "can we build a neural network?" but "can we build a business around one?"
Five years later, in 2017, the "Attention Is All You Need" paper introduced the transformer architecture. Transformers made the same basic architecture handle language, vision, and eventually code. This made neural networks more general-purpose, more scalable, and easier to deploy across different domains.
Then came 2020 and GPT-3. With 175 billion parameters, it was the largest neural network anyone had seen. More importantly, OpenAI released it as an API. This shifted the commercialization pattern from "we trained a model" to "we ship a product." Developers could suddenly access state-of-the-art AI without training anything themselves.
The next wave hit in 2023-2025: the open-source explosion. Meta's Llama family, Mistral, and others made powerful models freely available. Suddenly, the bottleneck was not access to models. The bottleneck was everything else: infrastructure, product design, distribution, and unit economics. The question was no longer "can we build a neural network?" but "can we build a business around one?"
Stage 1: From Research Paper to Reproducible Model
Here is an uncomfortable truth: most research papers never reproduce. The code is not shared, the data is not clean, or the training process is so fragile that minor changes break everything. Researchers claim 95% accuracy, but independent teams struggle to break 70% when they try to run the code. This is the first valley of death.
Teams bleed money not on the model itself, but on the invisible infrastructure around it. They spend months cleaning labeled data and debugging fragile training pipelines. Documentation rarely helps someone else run the code. These unglamorous tasks separate a paper from a reproducible model.
This is why the rise of open-source weights matters so much. When researchers release the actual model weights, the training code, and example datasets, they dramatically increase the chances of reproduction. The model moves from "interesting idea" to "something you can actually build on." But even with open weights, most models still die here. They are too slow, too expensive, or too specialized to be useful outside the original research context.
Teams bleed money not on the model itself, but on the invisible infrastructure around it. They spend months cleaning labeled data and debugging fragile training pipelines. Documentation rarely helps someone else run the code. These unglamorous tasks separate a paper from a reproducible model.
This is why the rise of open-source weights matters so much. When researchers release the actual model weights, the training code, and example datasets, they dramatically increase the chances of reproduction. The model moves from "interesting idea" to "something you can actually build on." But even with open weights, most models still die here. They are too slow, too expensive, or too specialized to be useful outside the original research context.
Stage 2: From Reproducible Model to Shippable Product
This is where the demo-to-product valley opens up. You have a working model. Great. But can it handle 100,000 users a day? Can it respond in under 200 milliseconds? Does it gracefully handle edge cases, malformed inputs, or unexpected usage patterns? Does it have a user interface that does not require a PhD to operate?
The difference between a cool inference script and a shippable product is massive. One runs on your laptop when you remember to start it. The other runs 24/7, serves thousands of concurrent requests, logs errors, monitors performance, and updates without downtime. This stage requires a completely different skillset: software engineering, UX design, error handling, monitoring, and customer support.
A model with 90% accuracy that responds in 100ms beats a 95% model that takes 2 seconds and crashes on edge cases every time. The teams that make it through this stage start thinking about the user experience before the model is perfect. They ship early, iterate based on real feedback, and treat the model as one component of a larger system.
The difference between a cool inference script and a shippable product is massive. One runs on your laptop when you remember to start it. The other runs 24/7, serves thousands of concurrent requests, logs errors, monitors performance, and updates without downtime. This stage requires a completely different skillset: software engineering, UX design, error handling, monitoring, and customer support.
A model with 90% accuracy that responds in 100ms beats a 95% model that takes 2 seconds and crashes on edge cases every time. The teams that make it through this stage start thinking about the user experience before the model is perfect. They ship early, iterate based on real feedback, and treat the model as one component of a larger system.
Stage 3: From Product to Scale
You have got a product. People are using it. Now what? This is where the infrastructure bill hits. Inference costs multiply. Latency becomes a bottleneck. Your cloud provider sends you a bill that makes you question your life choices.
Founders cannot simply throw more servers at the problem. They must quantize models to save compute, distill smaller models to mimic larger ones, and cache frequent responses. Each choice has tradeoffs: speed versus accuracy, cost versus quality, flexibility versus performance.
The infrastructure layer is what most founders underestimate. They think the model is the hard part. But at scale, the model is just one piece. You need load balancing, auto-scaling, monitoring, A/B testing, version management, and rollback capabilities. You need to track unit economics from day one: what does it cost to serve one request, and what do you charge for it? If the math does not work at 100 users, it definitely will not work at 100,000.
Founders cannot simply throw more servers at the problem. They must quantize models to save compute, distill smaller models to mimic larger ones, and cache frequent responses. Each choice has tradeoffs: speed versus accuracy, cost versus quality, flexibility versus performance.
The infrastructure layer is what most founders underestimate. They think the model is the hard part. But at scale, the model is just one piece. You need load balancing, auto-scaling, monitoring, A/B testing, version management, and rollback capabilities. You need to track unit economics from day one: what does it cost to serve one request, and what do you charge for it? If the math does not work at 100 users, it definitely will not work at 100,000.
Stage 4: From Scale to Market Position
A great model is not a great business. This is where many technically brilliant companies stumble. You can have the best neural network in the world, but if no one knows about it, if they do not trust it, if they cannot afford it, or if they cannot figure out how to use it-you lose.
Distribution is everything. Trust is earned through reliability, transparency, and support. Pricing is a strategic decision, not just a reflection of your compute costs. Sales, marketing, customer success, documentation, tutorials, case studies-this is the unglamorous work that separates products from businesses.
The pattern is simple: the model is the engine, the product is the car. No one buys an engine. They buy a car that gets them from A to B reliably, comfortably, and affordably. The companies that win at this stage understand that their neural network is a means to an end, not the end itself. They invest in brand building, community, partnerships, and the boring operational excellence that keeps customers coming back.
Distribution is everything. Trust is earned through reliability, transparency, and support. Pricing is a strategic decision, not just a reflection of your compute costs. Sales, marketing, customer success, documentation, tutorials, case studies-this is the unglamorous work that separates products from businesses.
The pattern is simple: the model is the engine, the product is the car. No one buys an engine. They buy a car that gets them from A to B reliably, comfortably, and affordably. The companies that win at this stage understand that their neural network is a means to an end, not the end itself. They invest in brand building, community, partnerships, and the boring operational excellence that keeps customers coming back.
What the Successful Crossers Do Differently
So what separates the neural networks that make it to market from the ones that die in the lab? The pattern is clear:
- They eliminate a specific, expensive task - Not "we have a cool model," but "we cut this workflow from three days to three minutes."
- They build the UX before the model is perfect - They ship when the model is "good enough" and improve based on real user feedback.
- They invest in data flywheels early - Every user interaction makes the product better, creating a defensible moat.
- They keep the model swappable - They do not lock themselves into one architecture. If a better model comes along, they integrate it.
- They treat infrastructure as a product, not a cost center - MLOps, monitoring, and deployment are competitive advantages, not afterthoughts.
- They price for value, not for compute - They charge based on the problem they solve, not the GPU hours they consume.
These are not technical insights. They are business insights. And that is exactly the point.
Naming the Stack: Neural Domains on Ainame24
Every successful AI product has two critical layers: the entry layer where users first engage, and the scale layer where the neural network runs at production capacity. These layers need names that communicate their purpose clearly. That is where strategic domain naming comes in. Ainame24 is a curated showcase where each name links to its official Afternic or Sedo listing, helping founders claim their position in the neural stack.
NeuralEntry.com - The Entry Layer
NeuralEntry.com acts as the gateway, the portal, the first thing a user or developer touches when entering a neural ecosystem. The name combines "Neural" with "Entry" to create a clear semantic meaning: this is where you access AI systems. It is perfect for AI onboarding products, model portals, API gateways, educational platforms, or any service that serves as the entry point into the world of neural networks.
The strength of this name is its clarity. When someone sees NeuralEntry, they immediately understand: this is how I get in. It is modern, technological, and positions the brand as a professional gateway to AI capabilities. For products focused on democratizing access to neural networks or simplifying the onboarding process, this domain instantly communicates the value proposition.
The strength of this name is its clarity. When someone sees NeuralEntry, they immediately understand: this is how I get in. It is modern, technological, and positions the brand as a professional gateway to AI capabilities. For products focused on democratizing access to neural networks or simplifying the onboarding process, this domain instantly communicates the value proposition.
NeuralGrand.com - The Scale Layer
NeuralGrand.com powers the opposite end of the stack: where neural networks run at grand, production-ready scale. The name evokes power, magnitude, and premium quality. It is ideal for foundation-model infrastructure, large-scale inference platforms, enterprise neural systems, or any ambitious AI project that needs to signal serious capability.
Where NeuralEntry is about access, NeuralGrand is about power. You choose this name when you are building something massive-enterprise-grade automation, complex data analysis at scale, or next-generation intelligent systems. The domain carries an emotional message of greatness and technological leadership, making it perfect for B2B platforms or consumer products that want to position themselves at the premium end of the market.
Where NeuralEntry is about access, NeuralGrand is about power. You choose this name when you are building something massive-enterprise-grade automation, complex data analysis at scale, or next-generation intelligent systems. The domain carries an emotional message of greatness and technological leadership, making it perfect for B2B platforms or consumer products that want to position themselves at the premium end of the market.
What This Means for Founders Building Neural Products
If you are building a neural network product today, here is the honest playbook: start at the user pain, not the model size. Do not fall in love with your architecture. Fall in love with the problem you are solving. Name your entry and your scale clearly from day one. If you are building the gateway, own that positioning. If you are building the infrastructure, make it undeniable.
The market is maturing. The open-source wave has democratized access to powerful models. The bottleneck is no longer technology. It is product thinking, distribution, and strategic positioning. Category-defining neural brands will compound as the market matures, but only if they make it across all five stages. The naming of the stack is happening now, and the domains you claim today will define your position tomorrow. You can explore neural and AI domain collections on Ainame24 to find names that match your vision.
The market is maturing. The open-source wave has democratized access to powerful models. The bottleneck is no longer technology. It is product thinking, distribution, and strategic positioning. Category-defining neural brands will compound as the market matures, but only if they make it across all five stages. The naming of the stack is happening now, and the domains you claim today will define your position tomorrow. You can explore neural and AI domain collections on Ainame24 to find names that match your vision.
The Road Ahead
The lab-to-market gap will not disappear. It might narrow as tools improve, but it will always exist. Research will always be ahead of production. The cutting edge will always be unstable. But the tools for crossing the gap keep getting better: better model serving frameworks, better quantization techniques, better infrastructure, better distribution channels.
The winners will not be the ones with the lowest loss on a benchmark. They will be the ones who ship. Who listen to users. Who iterate. Who understand that a neural network is only as valuable as the problem it solves in someone's hands. The next wave of AI companies will not be defined by their models. They will be defined by their ability to cross the gap.
The naming of the stack is happening now. The entry points are being claimed. The scale layers are being built. The question is not whether neural networks will transform industries. It is which ones will make it out of the lab and into the market. The crossing starts with a name, an entry point, and a plan for scale.
The winners will not be the ones with the lowest loss on a benchmark. They will be the ones who ship. Who listen to users. Who iterate. Who understand that a neural network is only as valuable as the problem it solves in someone's hands. The next wave of AI companies will not be defined by their models. They will be defined by their ability to cross the gap.
The naming of the stack is happening now. The entry points are being claimed. The scale layers are being built. The question is not whether neural networks will transform industries. It is which ones will make it out of the lab and into the market. The crossing starts with a name, an entry point, and a plan for scale.
Conclusion
The neural networks that change the world are not the ones with the lowest loss on a paper. They are the ones that made it to the market. Every crossing starts with understanding the five stages, respecting the challenges at each level, and building the right team for the right phase. It starts with a name that positions you clearly, an entry strategy that brings users in, and a scale architecture that grows with demand. The gap is real, but it is crossable. And the companies that make it will be the ones who remember: research is the beginning, but the market is the destination.